> For the complete documentation index, see [llms.txt](https://docs.rootcause.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.rootcause.ai/user-guide/ontology-concepts.md).

# Build Ontology

When your data finishes importing, RootCause automatically builds an ontology. It scans every dataset, identifies each column's type and role, and maps connections between columns that represent the same concept across different datasets. You do not need to create it — it is ready by the time your data is processed.

***

## What the ontology does

The ontology is the semantic layer that makes everything downstream possible. When "customer\_id" in your sales data and "cust\_id" in your support data are recognized as the same concept, RootCause can join those datasets automatically. When a column is classified as a Time concept, causal discovery respects temporal ordering. When a column is classified as an Identifier, it is used as a join key rather than treated as a variable in the causal model.

***

## Reviewing your ontology

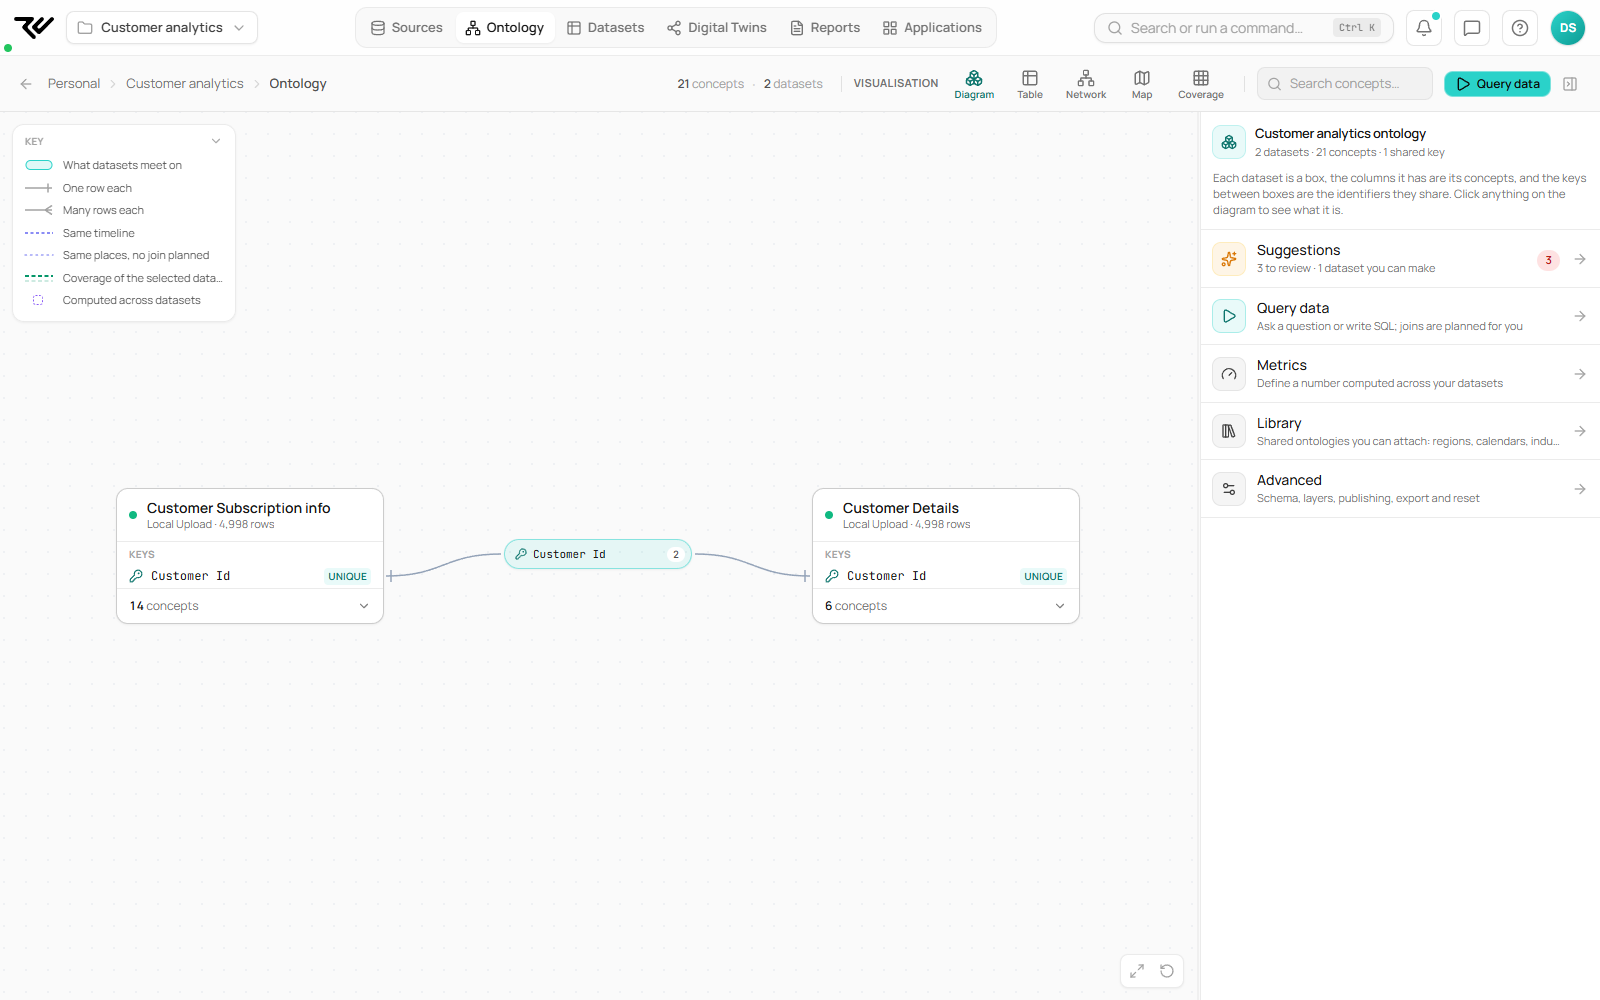
Open **Ontology** in the top navigation bar. The page opens on the **Diagram**: each dataset is a box listing its keys, and a key two datasets share sits between them, wired to both. Click anything on the diagram to see what it is in the right panel.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-68545034d168eeac997c4223c0b7b9f96edf95f7%2Frc-ontology-diagram-view.png?alt=media" alt="Ontology Diagram view with two dataset boxes, Customer Subscription info with 14 concepts and Customer Details with 6, each listing Customer Id as a unique key, joined through a shared Customer Id key between them"><figcaption><p>The Diagram view. Customer Subscription info and Customer Details each hold Customer Id as a unique key, and the diagram joins them on it.</p></figcaption></figure>

The **Visualisation** toggle at the top of the page offers five views: **Diagram**, **Table**, **Network**, **Map** and **Coverage**. Map and Coverage are workspace-only; the organisation-level ontology shows Diagram, Table and Network. The page reopens on the view you last chose.

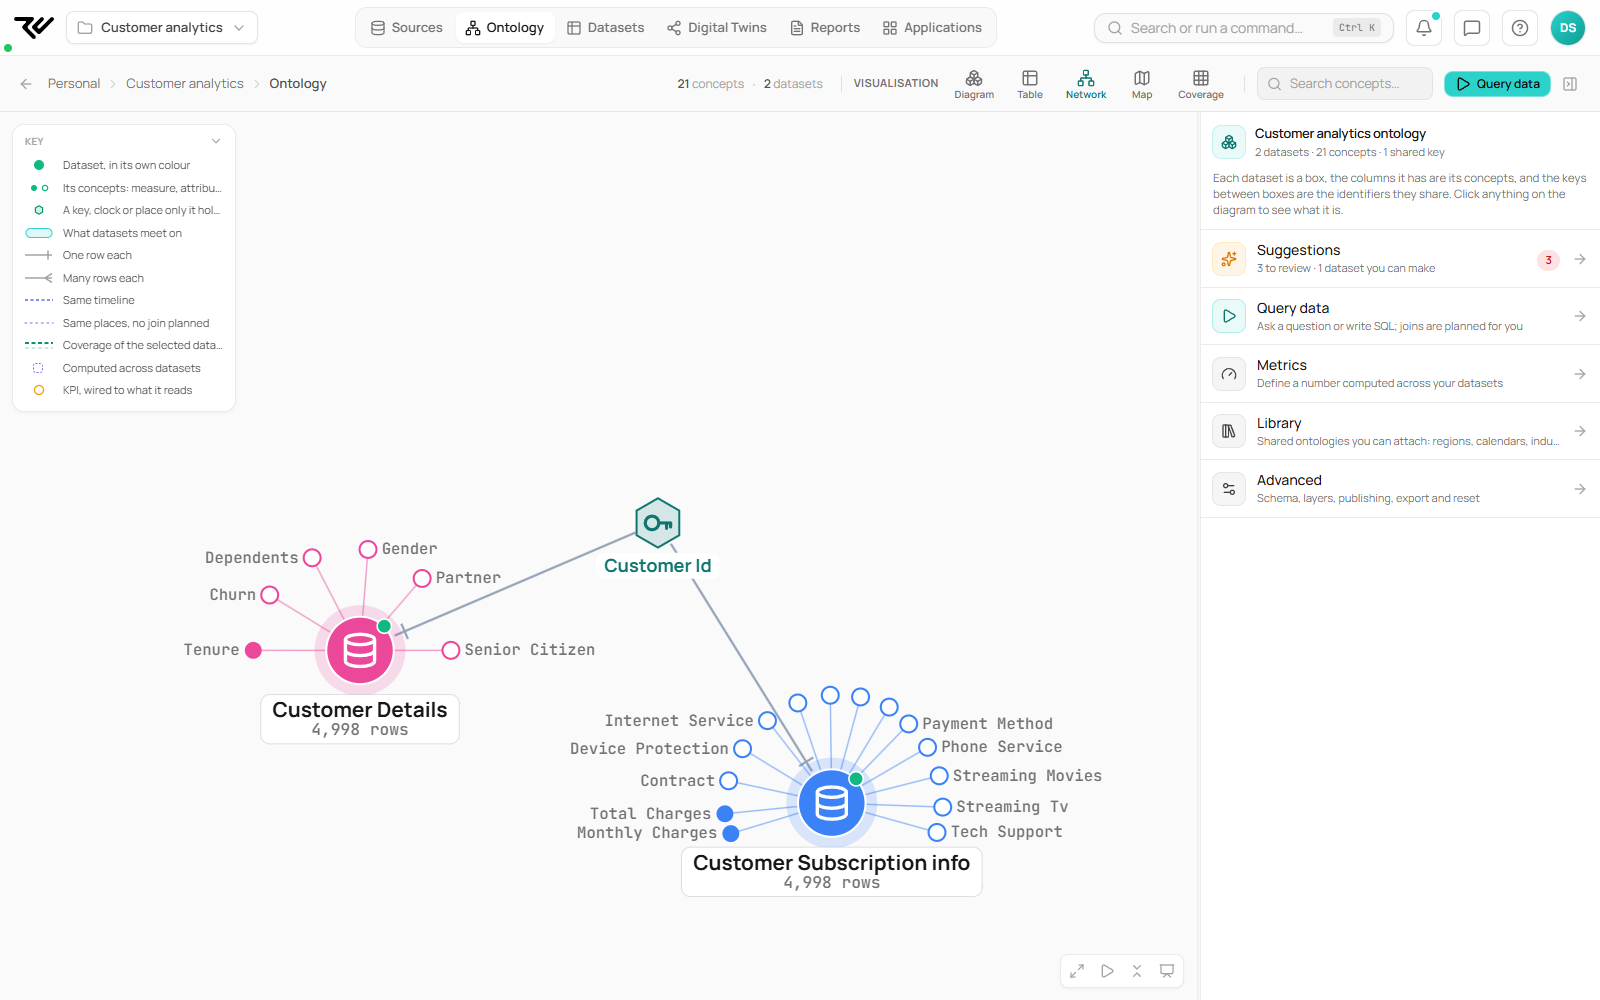
The **Network** view draws each dataset as a hub in its own colour with its concepts fanned above it: the keys, clocks and places only that dataset holds as small hexagons, then its measures as filled dots and its attributes as hollow ones. Keys that several datasets share become hexagon hubs of their own, and KPIs are wired to the concepts they read. Clicking a dataset, key, spoke, concept or KPI shows its details in the right panel, as in the Diagram view, and the **Key** card in the corner explains every mark. The toolbar in the bottom corner fits the network to the view, builds it up again, folds every dataset's concepts back into it, and presents it full screen.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-aa48bda55b289495948d9009fad859a8e98944de%2Frc-ontology-network-view.png?alt=media" alt="Ontology Network view: Customer Details and Customer Subscription info as coloured hubs with their concepts fanned above them, Tenure, Monthly Charges and Total Charges drawn as filled measure dots, joined through a shared Customer Id key hexagon"><figcaption><p>The Network view. Each dataset is a hub with its concepts fanned above it; measures such as Monthly Charges are filled, attributes hollow, and the shared Customer Id key is the hexagon between the two datasets.</p></figcaption></figure>

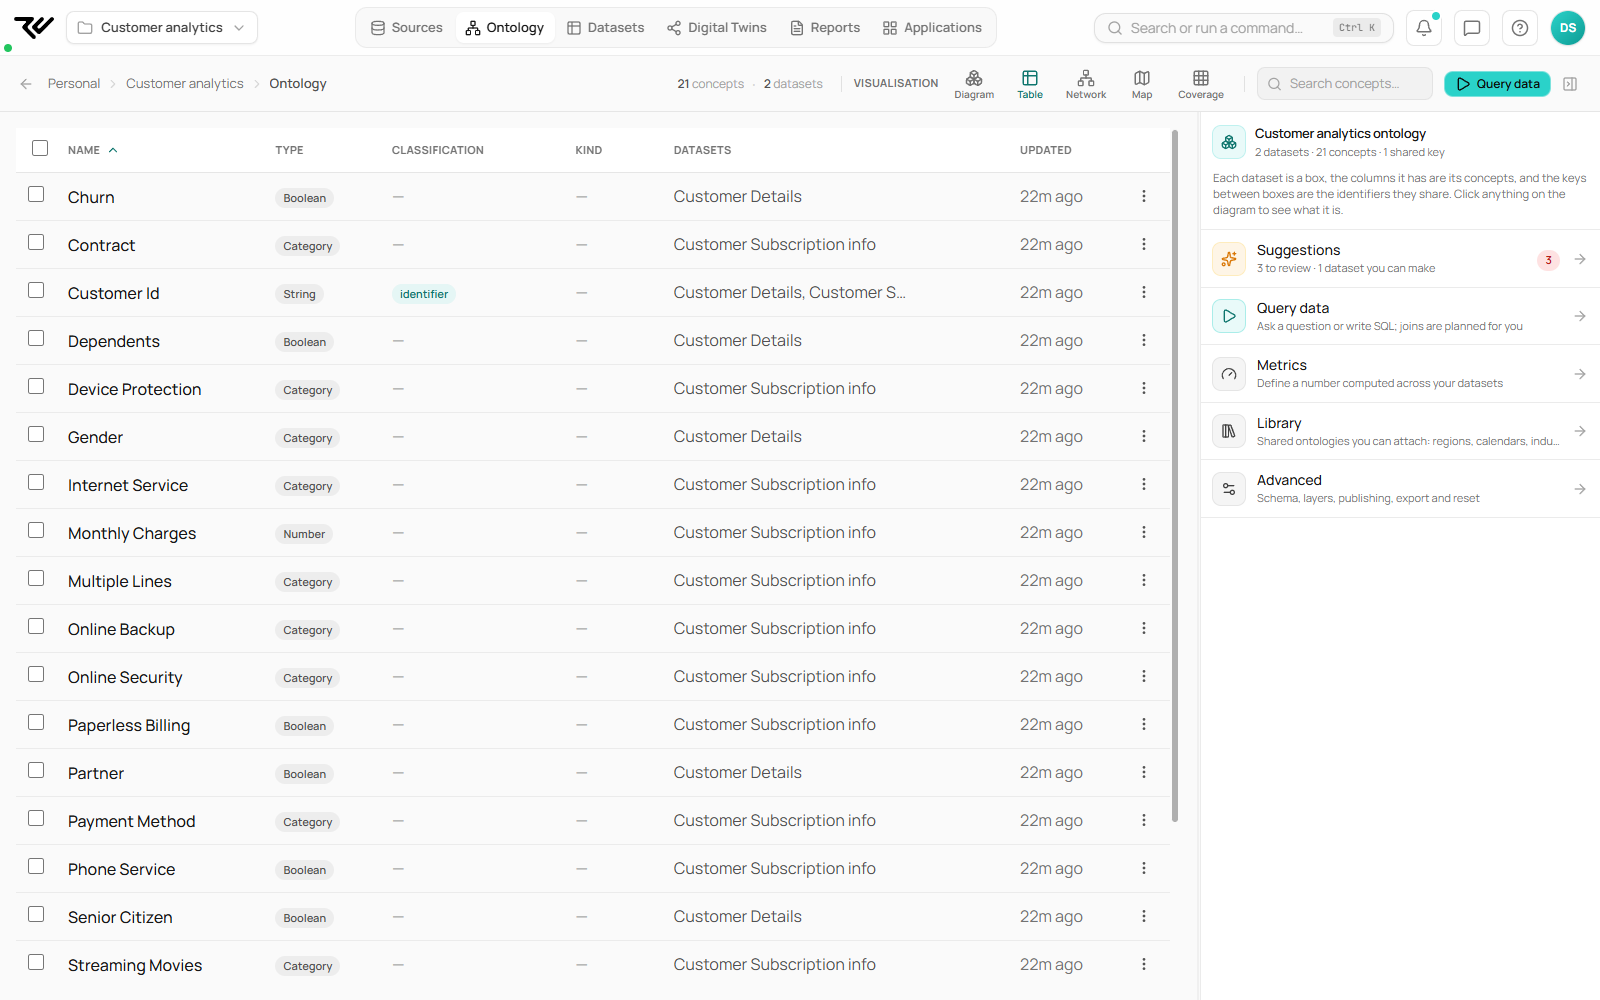
The **Table** view lists the concepts as a sortable table, the fastest way to check that identifiers and time fields have been correctly detected.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-8e52d322fe4af96d81f6e30ab37968de2720cb49%2Frc-ontology-card-view.png?alt=media" alt="Ontology Table view listing concepts with their type, classification, datasets, and last update, with Customer Id classified as an identifier held by both datasets"><figcaption><p>The Table view. Here Customer Id is the only classified concept, an identifier shared by both datasets.</p></figcaption></figure>

The right panel groups the ontology's actions:

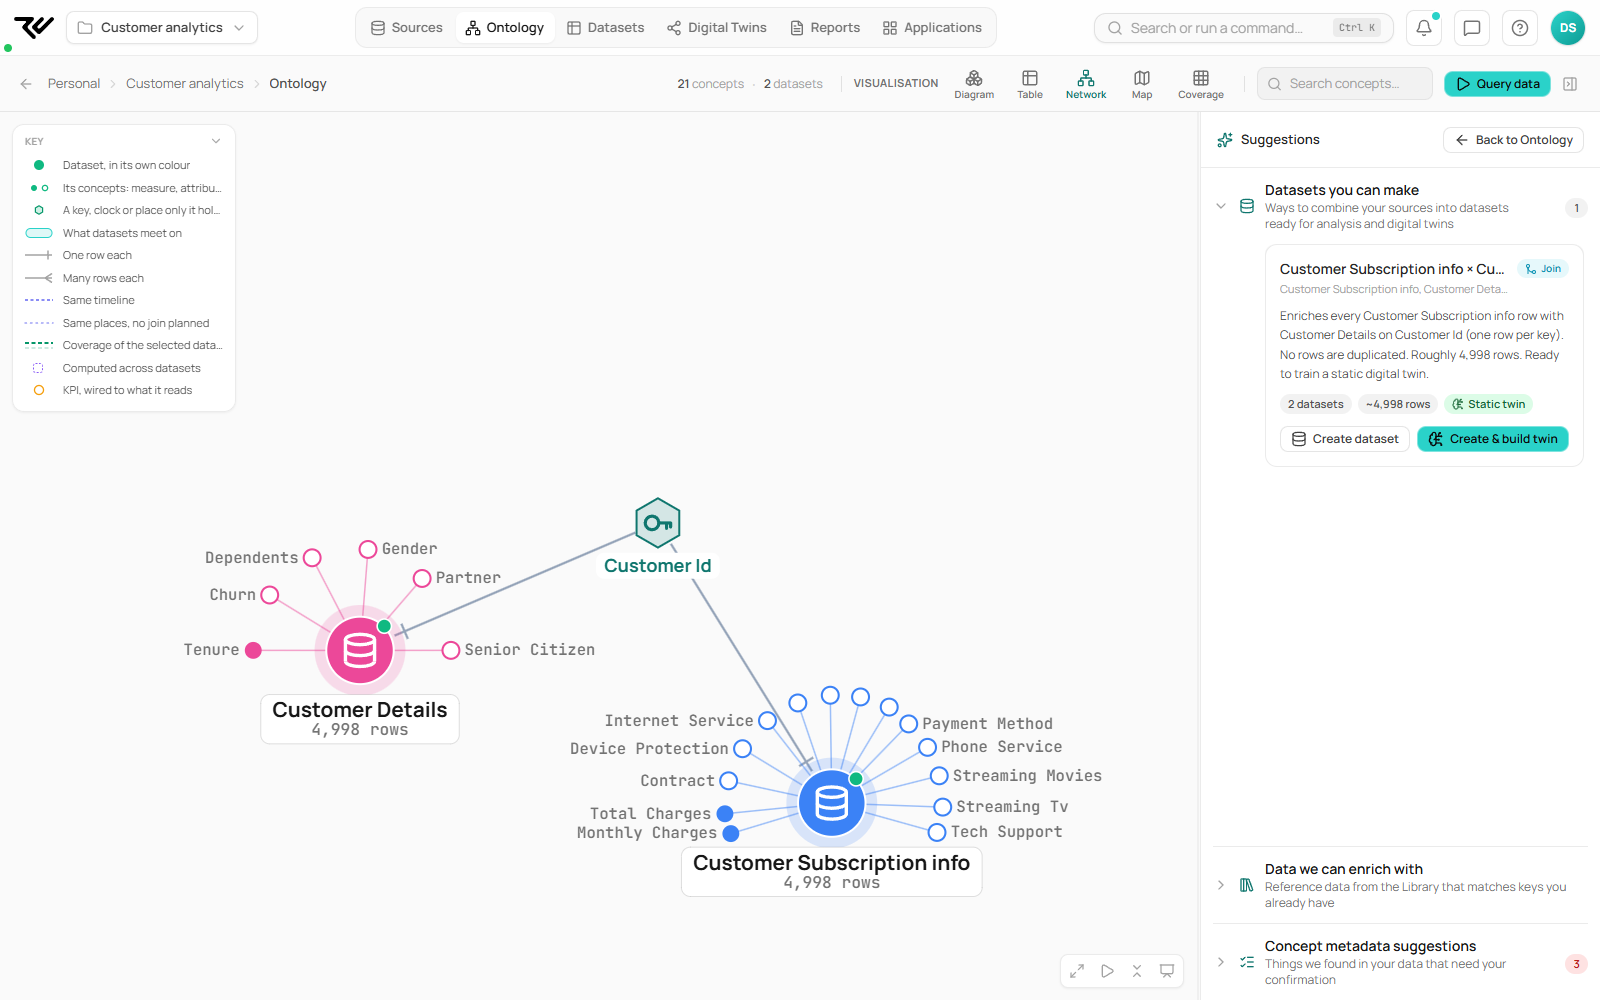
* **Suggestions** — what RootCause found that needs you. **Datasets you can make** lists "Ways to combine your sources into datasets ready for analysis and digital twins": joins on shared identifier concepts, time-based alignments, mixed joins, and stacks of similarly-shaped files. It is the bridge between your ontology and Step 3. Below it, **Data we can enrich with** offers reference data from the Library that matches keys you already have, and **Concept metadata suggestions** lists what extraction proposed and wants you to confirm, such as a column marked as an outcome or a driver.
* **Query data** — ask a question or write SQL across your datasets; joins are planned for you.
* **Metrics** — define a number computed across your datasets.
* **Library** — shared ontologies you can attach, such as regions, calendars and industry codes.
* **Advanced** — define a schema before data arrives, attach from or publish to the Library, export, add a computed concept, and reset.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-e46e8cd585e4976f5db2e5852ce53fe28e37d620%2Frc-ontology-recommended-dataset.png?alt=media" alt="Suggestions panel open on Datasets you can make, proposing a Customer Subscription info × Customer Details join on Customer Id, one row per key, about 4,998 rows, tagged Static twin, with Create dataset and Create &#x26; build twin buttons"><figcaption><p>Suggestions, open on Datasets you can make. <strong>Create dataset</strong> builds the join; <strong>Create &#x26; build twin</strong> goes straight on to the twin builder.</p></figcaption></figure>

***

## Concept classifications

Concepts can be classified as Identifier, Time, or Location — anything unclassified appears as Entity:

**Identifier** — unique keys that link records across sources: Customer ID, Product SKU, Order Number. These serve as join keys and are not used as causal variables.

**Time** — temporal columns: Order Date, Timestamp, Created At. Defines event ordering for time-series analysis and temporal Digital Twins.

**Location** — geographic columns: City, Region, Postal Code. Enables location-based filtering and analysis.

**Entity** — everything without a specific classification: Revenue, Quantity, Churn, Monthly Charges. These are the variables that participate in causal relationships.

A concept's details also mark it **Composite** when it is one of several columns that together identify a row of its dataset, such as a store and a week. Each on its own repeats; only the combination is unique.

***

## Refining your ontology

For most projects the auto-generated ontology is accurate enough to proceed. If a concept has been misclassified, or if two columns that represent the same thing were created as separate concepts, you can correct this at any time — reclassify a concept, merge two into one, or split one that incorrectly combines two different things. Concepts can also carry tags: freeform labels you attach to a concept so that related concepts can be found and treated consistently in analysis.

***

## Export and reset

Both sit under **Advanced** in the right panel:

* **Export ontology** — download the whole ontology as **JSON**, or its node and edge topology as **GraphML** for graph tools, for use elsewhere or as a snapshot before making large changes.
* **Reset ontology** — delete all concepts and re-run extraction for the workspace or chosen sources.

{% hint style="warning" %}
**Reset is destructive.** All manual refinements — reclassifications, merges, tags — are lost when the ontology is re-extracted. Export the ontology first if you want a record. Use reset only when the ontology has drifted too far to repair by hand.
{% endhint %}

***

## Next step

With the ontology in place, RootCause knows how your datasets connect. [Step 3: Build 360 Table](/user-guide/data-views.md) walks through creating the single analysis-ready dataset that the causal engine trains on.