> For the complete documentation index, see [llms.txt](https://docs.rootcause.ai/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.rootcause.ai/more-details/digital-twin/simulation-types/intervention.md).

# Intervention

Intervention asks the [Digital Twin](/more-details/digital-twin.md) a counterfactual question: what would happen to a target metric if we changed a variable?

Unlike a [prediction](/more-details/digital-twin/simulation-types/prediction.md), which estimates an outcome given known inputs, an intervention reaches into the causal graph and forces a variable to a new value. Every downstream variable adjusts according to its causal mechanism, and the change in the target metric is reported with a confidence interval.

For the workflow that produces a Digital Twin in the first place, see [Step 5: Build Digital Twin](/user-guide/creating-digital-twin.md).

***

## Starting a simulation

Open a Digital Twin from the Digital Twins list, open its **Simulations** row (or click **Run Simulation** in the toolbar), then click **New Simulation**. This opens the [type picker](/more-details/digital-twin/simulation-types.md) — choose **Intervention**.

The setup form has three sections plus a configuration summary at the foot. Each section answers part of the question being asked: *what changes, how do we measure the effect, and across which subgroups?*

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-baafe795f25188d8e31b09f5e1c582589c7a75ff%2Frc-intervention-new-simulation-blank.jpeg?alt=media" alt="The empty Intervention setup form, with Section 1 What will you change showing an unset variable picker and Section 2 Define success metrics starting below"><figcaption><p>The empty setup form. Sections build the experiment top to bottom.</p></figcaption></figure>

***

## Target and intervention

Two ideas drive every intervention simulation.

**The target.** The metric whose movement you care about — reducing churn, increasing average revenue per user, cutting handling time.

**The intervention.** The lever you want to test against the target — what if every customer got online backup as part of their package, or month-to-month contracts came at a discount, or onboarding emails went out within an hour of signup?

The form takes them in the opposite order: Step 1 sets the intervention, Step 2 sets the metric. Fix the target in mind first — the intervention is only meaningful as a way to move it.

***

## Step 1: What will you change?

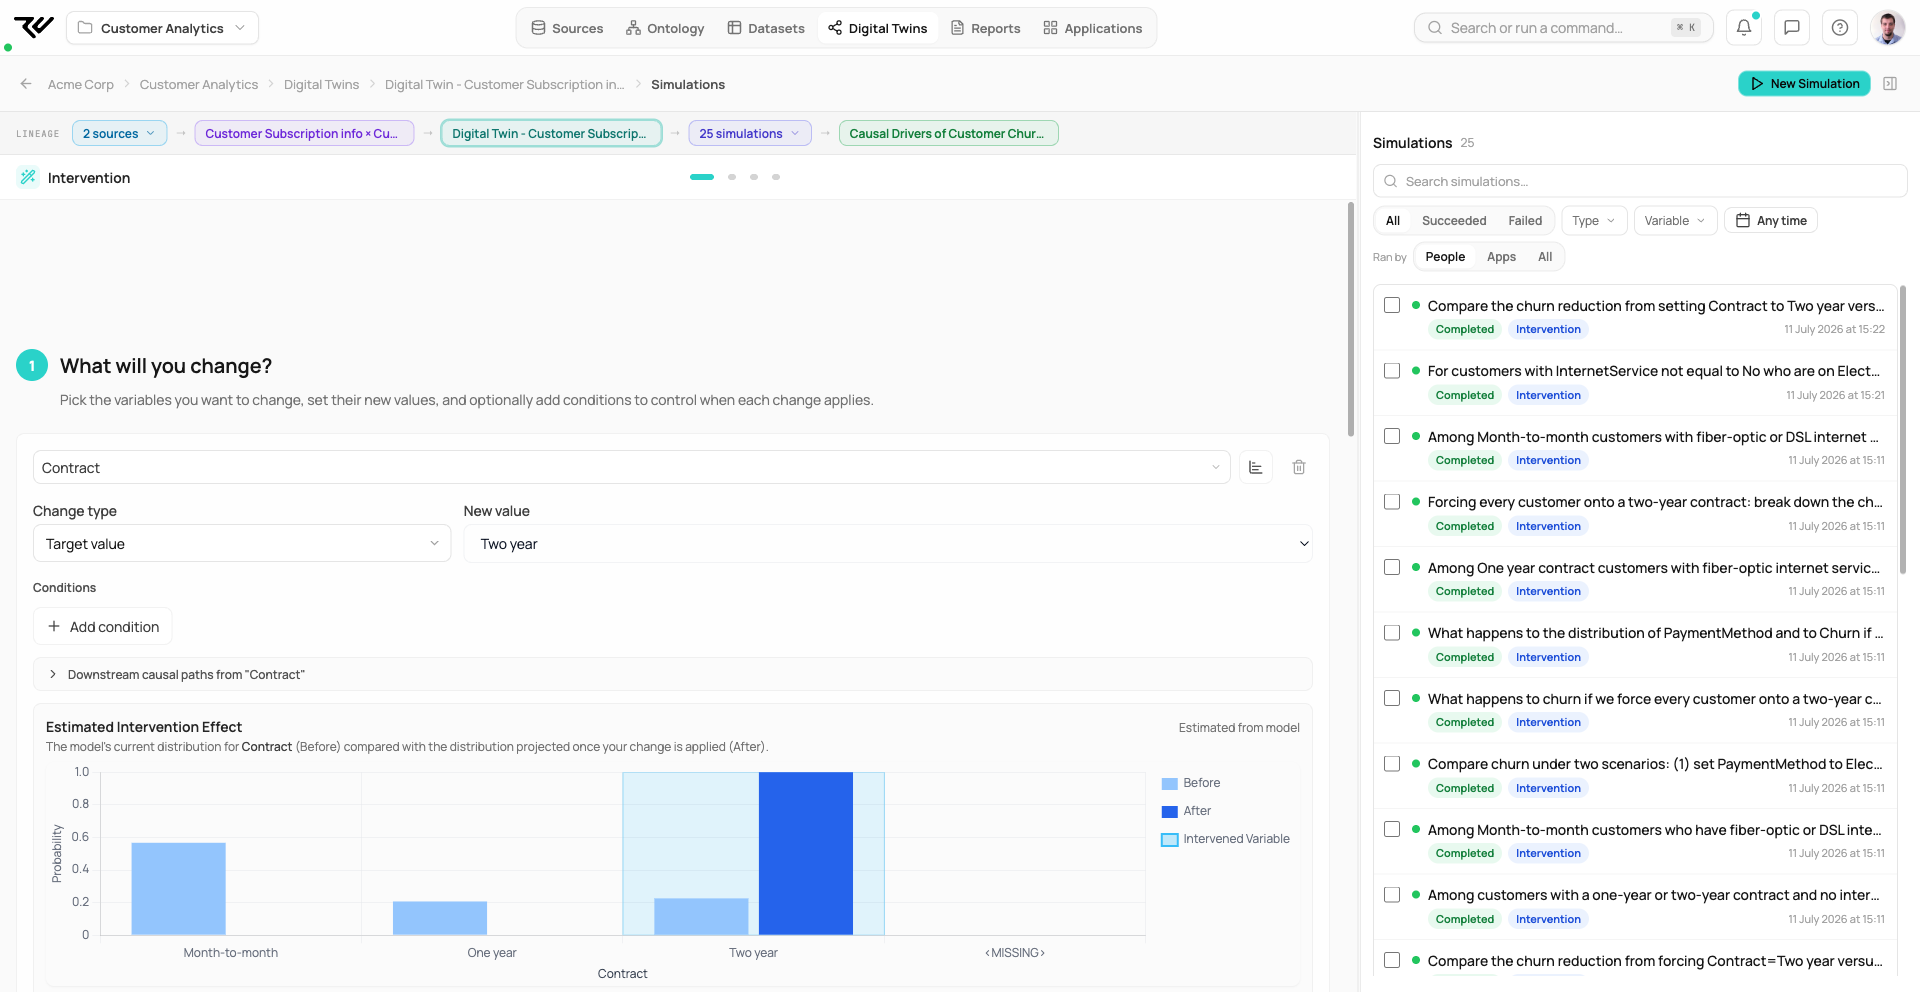
In the example, the change being tested is *move every month-to-month customer onto a two-year contract* — `Contract` set to `Two year`. The **change type** controls how the change is applied; *Target value* (shown) sets a single value uniformly across the population.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-a6865ac3165fccfecdbe222d31f269941816ddc2%2Frc-intervention-variable-picker.png?alt=media" alt="Section 1 of the Intervention form with Contract selected, Target value as the change type, Two year as the new value, and an Estimated Intervention Effect chart previewing the Before and After distribution of Contract"><figcaption><p>Choosing the variable, the change type, and the new value. The Estimated Intervention Effect preview shows how the chosen change shifts the variable's distribution before you run anything.</p></figcaption></figure>

For categorical variables, the **New value** dropdown lists every level the variable can take. For numeric variables, you enter a value directly.

Once a variable is picked, a **Downstream causal paths from "X"** row appears below. Expand it to see which downstream variables the change will propagate to according to the causal graph — useful for confirming what is in scope before you run.

**+ Add condition** restricts the intervention to records matching a filter. Without conditions, the change applies to the entire population. **+ Add intervention** layers a second change on top of the first to test a combined scenario.

***

## Step 2: Define success metrics

A metric is the number whose movement you want to read. At least one is required.

Each metric has a name, a unit (`# Count`, `$`, `%`, …), and a direction — *Higher is better* or *Lower is better*. The direction drives the color of the up and down arrows on the results page.

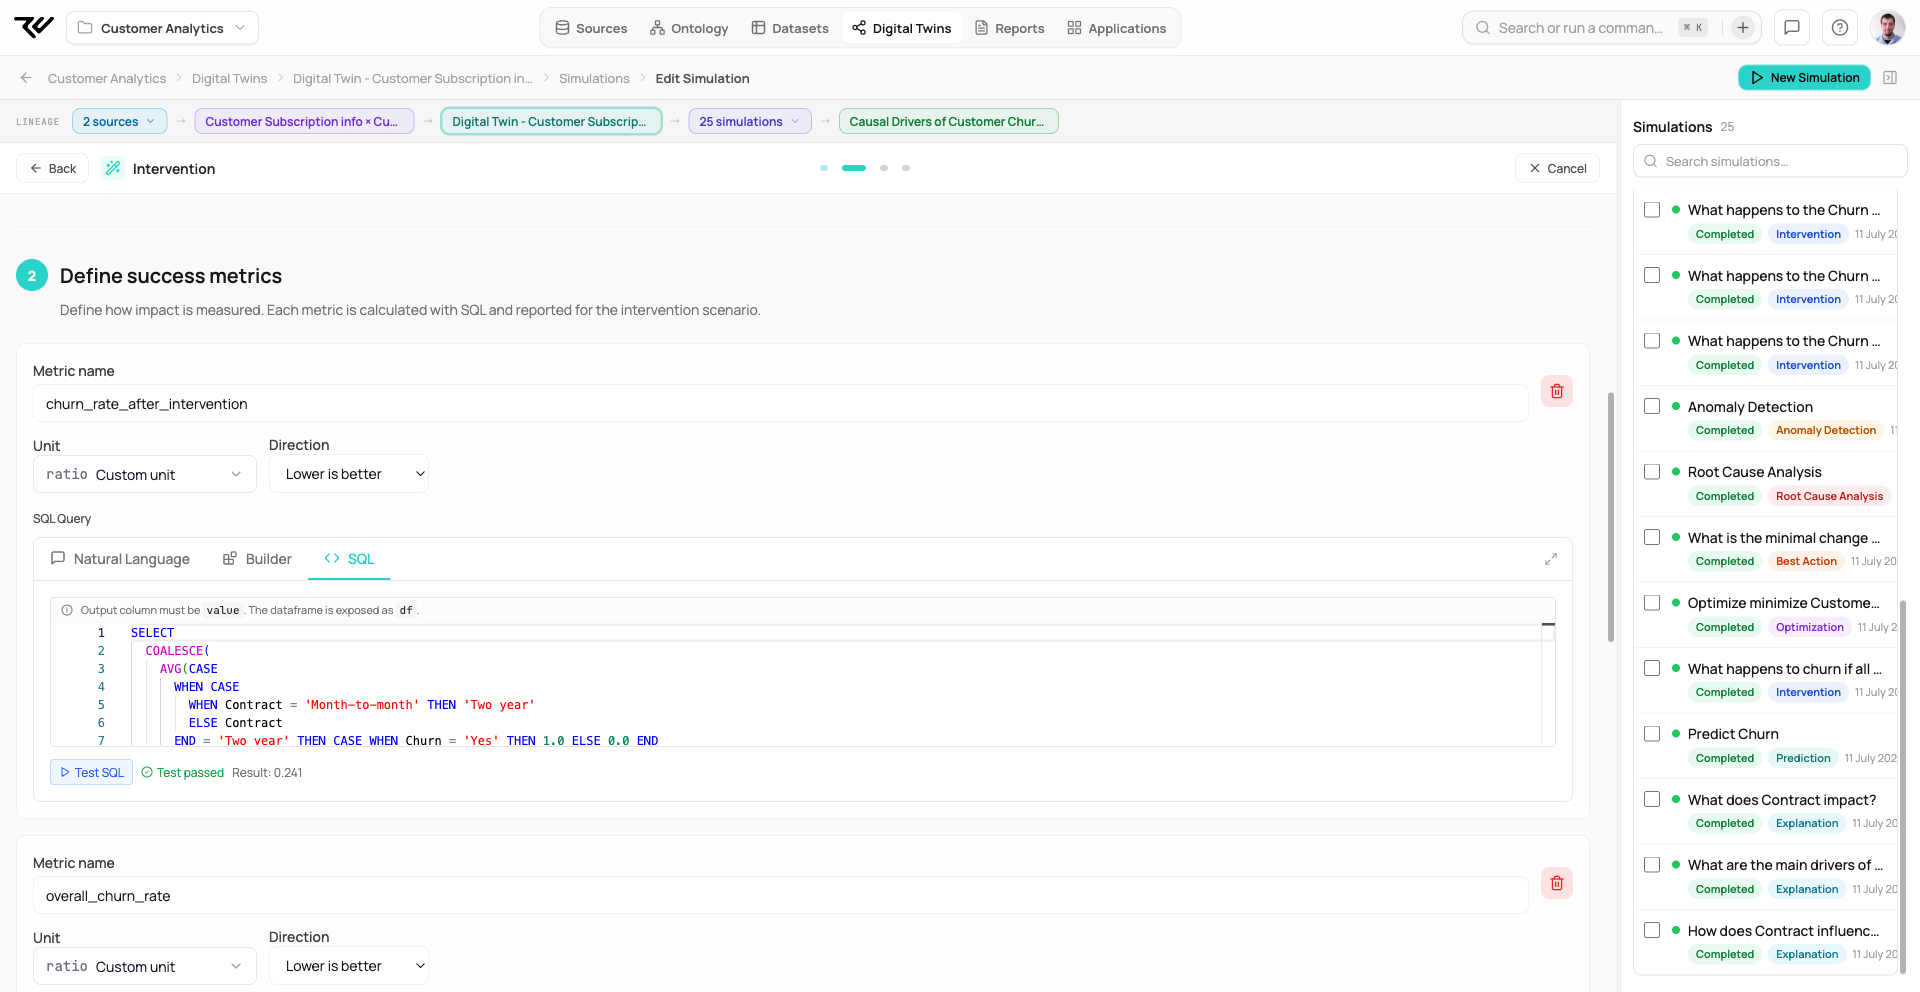
The query that computes the metric can be built three ways:

* **Natural Language** — describe the metric in plain English; the system writes the SQL.
* **Builder** — pick an aggregation and a column, optionally add filters. The simplest path for standard metrics.
* **SQL** — write the query by hand.

The three tabs stay in sync up to a point: once the SQL has been edited by hand, the Builder locks and offers **Reset Builder** to start fresh.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-e9d0371309db19394c77af8e16e15dbe84ebf1fe%2Frc-intervention-metric-tested.png?alt=media" alt="The Define success metrics section with metric name churn_rate_after_intervention, unit ratio, direction Lower is better, and the SQL tab open on a CASE-based churn query, with Test SQL reporting Test passed Result: 0.241; a second metric, overall_churn_rate, starts below"><figcaption><p>A metric on the SQL tab. The query must return a single <code>value</code> column; click <strong>Test SQL</strong> to run it against the underlying data; here it passes with a baseline churn rate of 0.241. A second metric, <code>overall_churn_rate</code>, is stacked below.</p></figcaption></figure>

In the Builder, tick **Return 0 instead of NULL when no rows match** if the metric should fail gracefully when filters exclude every record. Without it, an empty result returns NULL and the metric is undefined for that run. **+ Add metric** stacks further metrics; every one is reported separately in the result.

***

## Step 3: Segment definitions

Segments split the result into subgroups so you can compare the effect across them. Each segment is a named filter — for example, *Customers with a Partner* (`Partner equals Yes`) and *Customers without a Partner* (`Partner equals No`).

If no segments are defined, the simulation reports a single overall effect. Segments are optional but the effect of an intervention is rarely uniform across a population, so at least one segmentation is usually worth running.

***

## Configuration Summary

The card at the foot of the form mirrors back the experiment in plain English, with the version of the twin the simulation will run against.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-12a965121deb8fb697b2c8fbb2578662f4cdf27b%2Frc-intervention-new-simulation-ready.jpeg?alt=media" alt="The foot of the Intervention form: an empty Segment definitions section, the version picker set to 1.0.0, and the Configuration Summary reading What if we change Contract to Two year, only when Contract equals Month-to-month, to measure impact on churn_rate_after_intervention and overall_churn_rate, both with Aim: Lower, above the Validate and Run Simulation buttons"><figcaption><p>A completed configuration. The summary mirrors the experiment back in plain English: the change (Contract to Two year, applied only when Contract equals Month-to-month) and the two churn-rate metrics it will be judged on, both aiming lower. <strong>Validate</strong> checks the setup; <strong>Run Simulation</strong> launches it.</p></figcaption></figure>

***

## Reading the result

Clicking **Run Simulation** opens the result page. A progress bar reports the current stage while the simulation runs.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-87141050ca004f819b6d9cfacea40f10b298e1b1%2Frc-intervention-running.png?alt=media" alt="The Intervention run page mid-run, with a Simulation Running progress bar and the run&#x27;s configuration — OnlineSecurity to Yes, measured on churn_rate — restated in the sidebar"><figcaption><p>A run in progress; the sidebar restates what is being changed and measured. Static interventions usually complete in seconds.</p></figcaption></figure>

A completed run carries a green **Completed** pill and the actions **Create app**, **Export data** (CSV or JSON) and **Edit Config**; its duration is shown on the run's row in the list. The page leads with a deterministic headline sentence stating the effect in plain English. To get a PDF, tick the run in the list, click **Export 1 as report**, and use **Export PDF** in the report editor.

<figure><img src="https://1662811113-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FBXg3gZLR0e2Q8SzeQmql%2Fuploads%2Fgit-blob-d344b8c41f59388741b73b1422d76f5819902961%2Frc-intervention-result.png?alt=media" alt="A completed Intervention run: the headline sentence reporting that setting Contract to Two year moves the churn rate from 75.54% to 90.02%, statistically significant, above the segment scope selector, the baseline-versus-after chart, and the details panel showing Before, After, Change, the 95% CI and the verdict"><figcaption><p>A completed run. The headline sentence states the effect; the Segment selector above the numbers re-scopes everything below it; the chart sits beside the details panel.</p></figcaption></figure>

Below that, the result is laid out as a chart beside a details panel, with the causal subgraph underneath.

* **The chart** plots the metric you selected, baseline versus after. Where the run swept a range of values, a dose-response curve is drawn instead, with a confidence readout for the top of the range.
* **The details panel** reports **Before** and **After**, the absolute change, the percentage change, the 95% confidence interval and whether the difference is statistically significant. A very small p-value indicates the effect is unlikely to be due to chance.
* **The causal subgraph** shows the paths the effect travelled from the variable you changed to the metric you measured.
* **Segments** are a scope selector above the numbers, not a section: pick "All rows" or one segment, and the before, after and change figures are recomputed for just those rows. The confidence interval and the p-value are computed for the whole population, not per segment. The result is not shown for all segments at once.

***

## Past simulations

Past runs appear in the twin's run list, which the **Simulations** row on the twin's Home opens. The workflow is the same as for any other simulation type — see [Prediction › Past simulations](/more-details/digital-twin/simulation-types/prediction.md#past-simulations).

***

## Outside the UI

This simulation runs from the Python SDK and from the REST API, with the same configuration the wizard collects.

```python
>>> twin.intervene({"MonthlyCharges": rc.pct(-10)}, outcomes=["Churn"])
```

Over REST it is a scenario on `POST /api/v1/workspaces/{workspaceId}/simulations` with `"type": "intervention"`, or `temporal_intervention` / `panel_intervention` on the other twin kinds. Interventions measure their effect through metrics: name outcome columns with `outcomes=`, or write SQL with `rc.metric(...)`.

See [Working with Digital Twins](/api-and-integrations/sdk-getting-started/sdk-working-with-twins.md) for the SDK, and [Running Simulations over REST](/api-and-integrations/rest-running-simulations.md) for the request body.

***

## Other Simulation Types

* [Prediction](/more-details/digital-twin/simulation-types/prediction.md) — predict an outcome for a specific input.
* [Optimization](/more-details/digital-twin/simulation-types/optimization.md) — find the input combination that maximizes or minimizes a target.
* [Best Action](/more-details/digital-twin/simulation-types/best-action.md) — find the minimum change needed to reach a target outcome.
* [Explanation](/more-details/digital-twin/simulation-types/explanation.md) — understand the drivers and impacts behind an outcome.
* [Root Cause Analysis](/more-details/digital-twin/simulation-types/root-cause-analysis.md) — diagnose the cause of a specific abnormal value.
* [Anomaly Scan & Diagnosis](/more-details/digital-twin/simulation-types/anomaly-scan.md) — scan every variable for anomalies and diagnose each one.

See [Step 6: Run Simulations](/user-guide/simulations.md) — general overview.